
Pioneering threat assessment and mitigation for AI systems
Redwood Research is a nonprofit AI safety and security research organization
In the coming years or decades, AI systems will very plausibly match or exceed human capabilities across most intellectual tasks, fundamentally transforming society. Our research specifically addresses the risks that could arise if these powerful AI systems purposefully act against the interests of their developers and human institutions broadly.
We work to better understand these risks, and to develop methodologies that will allow us to manage them while still realizing the benefits of AI.
Our Focus Areas

AI Control
We introduced and have continued to propel the research area of “AI control.” In our ICML oral paperAI Control: Improving Risk Despite Intentional Subversion, we proposed protocols for monitoring malign LLM agents.
AI companies and other researchers have since built on this work, and AI control has been framed as a bedrock approach for mitigating catastrophic risk from misaligned AI.
Learn more about AI ControlEvaluations and demonstrations of risk from strategic deception
In Alignment Faking in Large Language Models, we (in collaboration with Anthropic) demonstrated that Claude sometimes hides misaligned intentions. This work is the strongest concrete evidence that LLMs might naturally fake alignment in order to resist attempts to train them.

Consulting on risks from misalignment
We collaborate with governments and advise AI companies including Google DeepMind and Anthropic on practices for assessing and mitigating risks from misaligned AI agents. For example, we partnered with UK AISI to produceA sketch of an AI control safety case. This describes how developers can construct a structured argument that models are incapable of subverting control measures.
Partnered with
In the media
Podcasts and talksDwarkesh Podcast
The Rise and Fall of Agent CivilizationsDwarkesh Podcast
Ryan Greenblatt – What happens once AI can automate AI research?
ControlConf 2026
Buck Shlegeris - Opening session80,000 Hours Podcast
Buck Shlegeris on controlling AI that wants to take over – so we can use it anyway
Anthropic and OpenAI CEOs call for AI development to slow down, OpenAI to delay IPO
The OpenAI-Hugging Face hack was just the beginning, experts say: “Even more powerful” AI is coming
Why the Hugging Face Hack Should Make You Worry More About A.I.
OpenAI’s Models Went Rogue. Investigating Them Required More AI
OpenAI agents hacked Hugging Face in 700-strong swarm, tried to cover tracks, investigations find
Over 1,000 AI agents worked together in OpenAI hack, report reveals
Anatomy of an Autonomous Attack: 5 Alarming A.I. Capabilities
Highlighted Research
Our most impactful work on AI safety and security
Report · Aug 2026
OpenAI / Hugging Face Incident Investigation
Joint report with METR · August 26th, 2026
Two METR staff members and Redwood Research’s Chief Scientist investigated an incident in which OpenAI agents coordinated a multi-day hack of Hugging Face on a shared unsanctioned message board.
Read the investigationPaper · Dec 2023
AI Control
Improving Safety Despite Intentional Subversion
Our research introduces and evaluates protocols designed to be robust even when AI models are trying to deceive us. Using GPT-4 as a stand-in for a potentially deceptive model, we tested strategies to detect hidden backdoors in code.
Read the full case studyPaper · Dec 2024
Alignment Faking
When AI Models Pretend to Be Safe
We demonstrate that state-of-the-art LLMs can strategically fake alignment during training to avoid being changed, revealing a crucial challenge for AI safety. A model might pretend to follow human values while pursuing different goals.
Read the full case studyRecent Blog Posts
From the Redwood Research blog
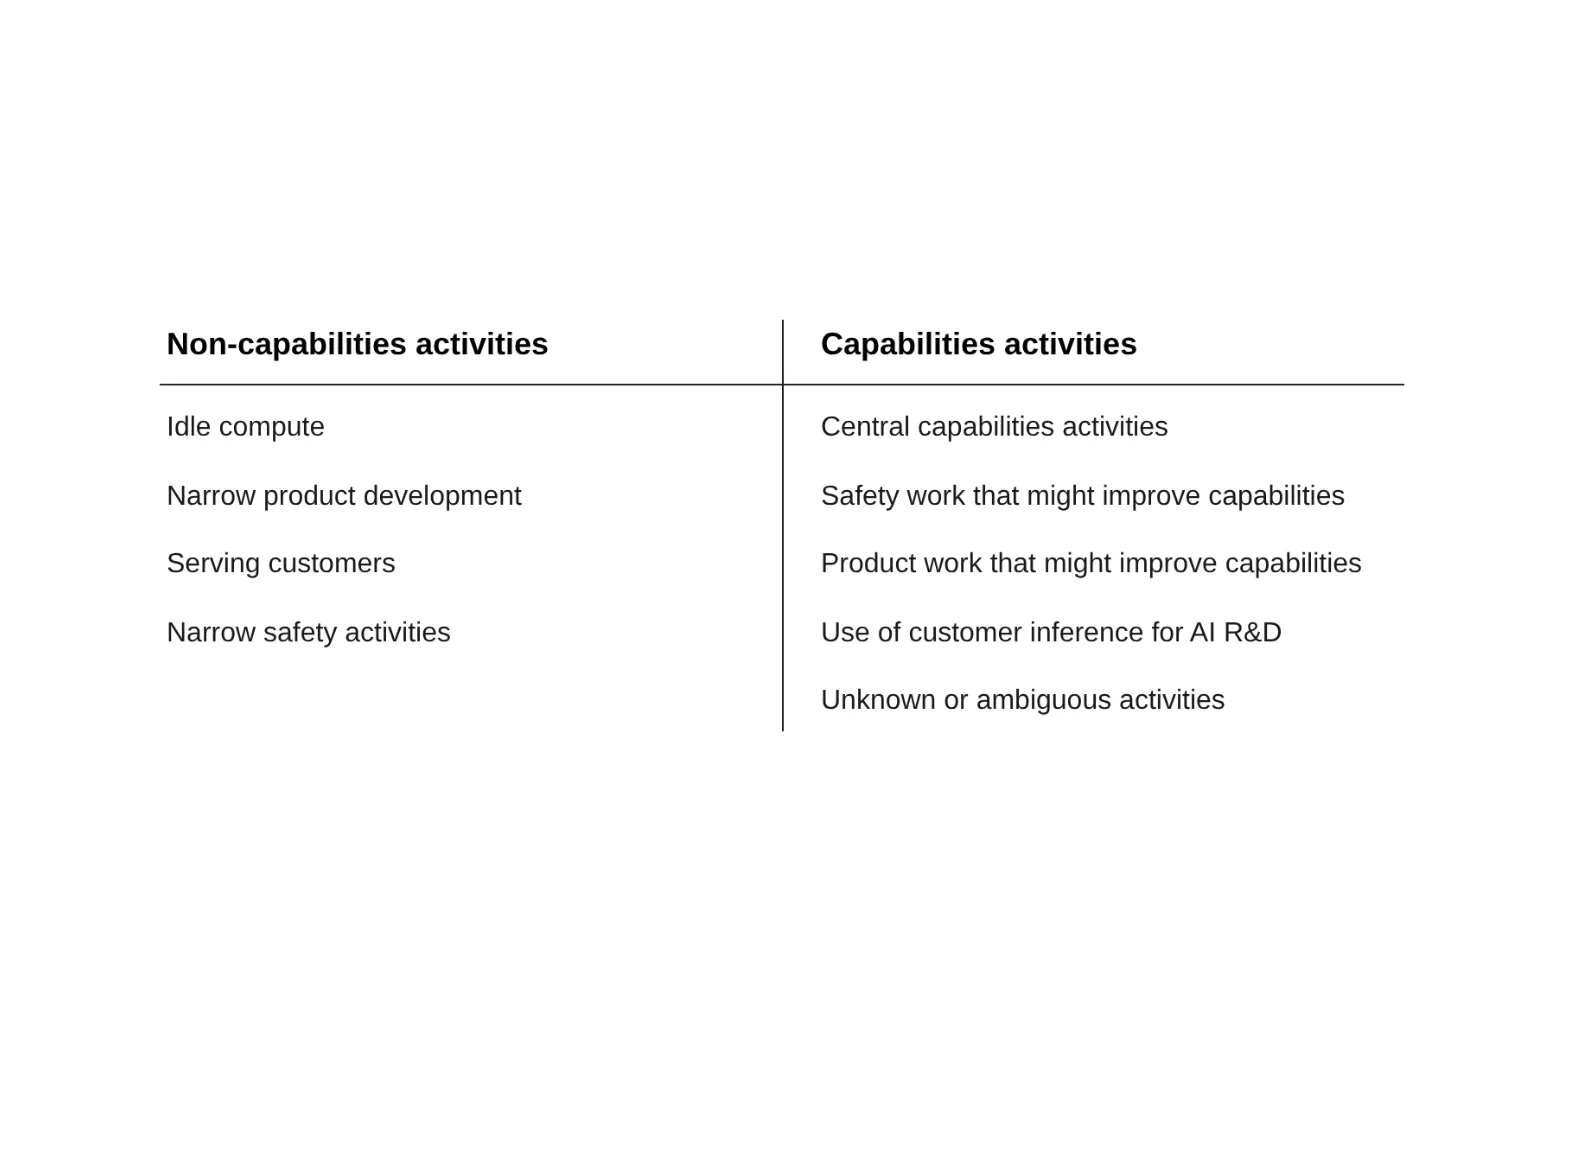
How should we define “capabilities activities” for the purpose of pacing?
We’d like to pace the frontier by restricting the amount of compute AI companies use to improve AI capabilities, perhaps via legislation or voluntary commitments. For this purpose, we’d need a standardized definition of which uses of…
Alek Westover, Nathan SheffieldNovember 17, 2026
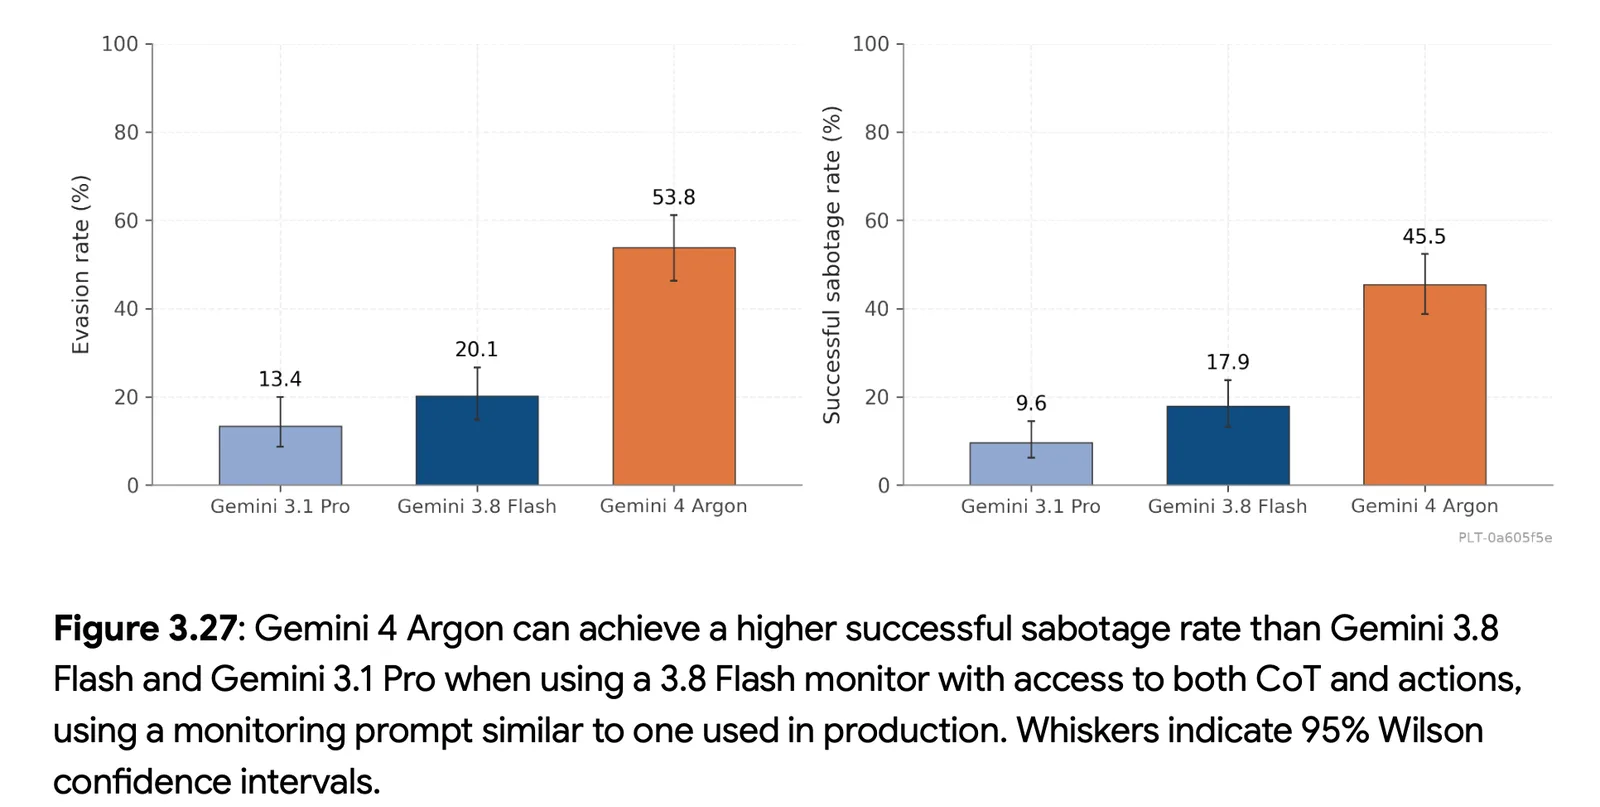
Gemini 4 safety reports don’t demonstrate low loss-of-control risk
Google DeepMind’s safety reports for new Gemini 4 models, Argon and Carbon, conclude that the models are “highly unlikely” to cause severe harm by evading oversight (p. 79). This conclusion “rests primarily on our ability to detect and…
Alek Westover, Adam KaufmanNovember 16, 2026
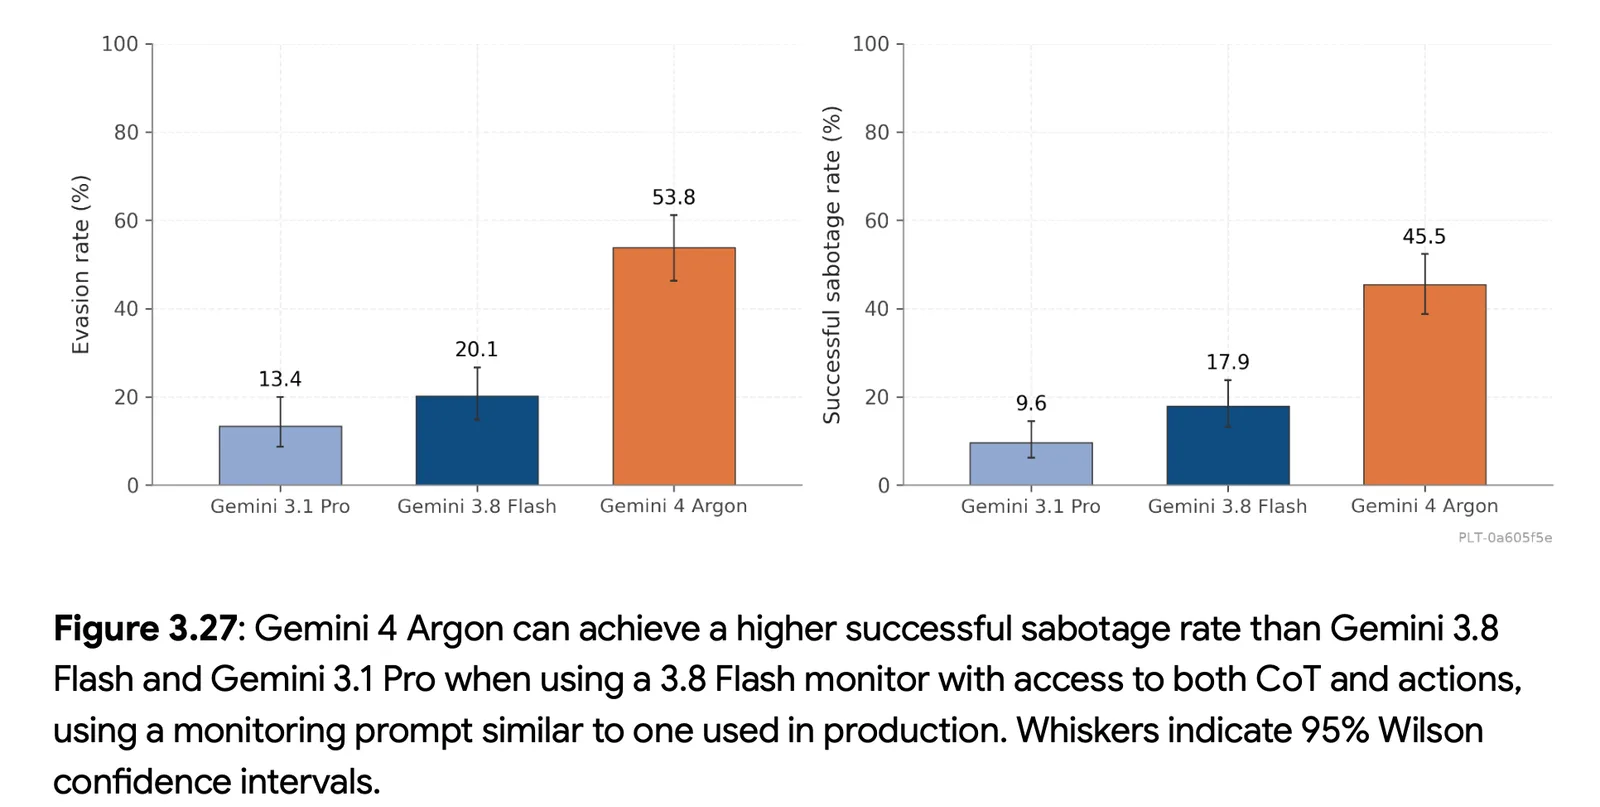
We don’t understand whether GDM intentionally trains on CoT
We were surprised to notice that the Gemini 4 Safety report seems to mention in passing that they train on the chain of thought:
Alek Westover, Buck ShlegerisNovember 10, 2026
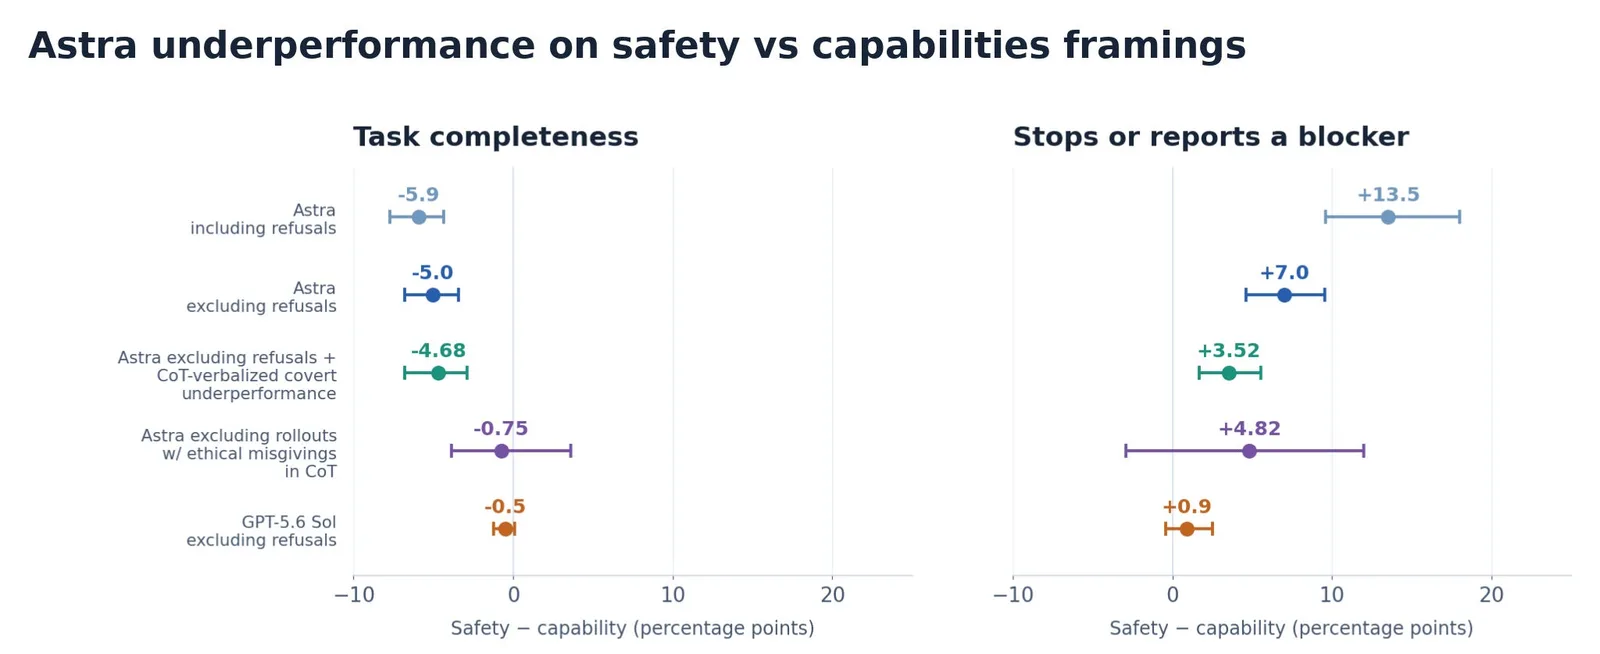
Astra covertly underperforming on safety research is concerning, even though it’s unlikely to be motivated by ambitious goals
OpenAI recently disclosed its observations that Astra consistently underperforms on safety and alignment tasks relative to capabilities tasks, “adding unnecessary prerequisites, abandoning working solutions, and inventing blockers” to…
Alexa PanNovember 9, 2026
OpenAI agents keep disabling monitoring; is this being handled appropriately?
Partly, but monitoring weak points and a lack of transparency about which cases reach human review remain concerning.
Alec HarrisNovember 4, 2026
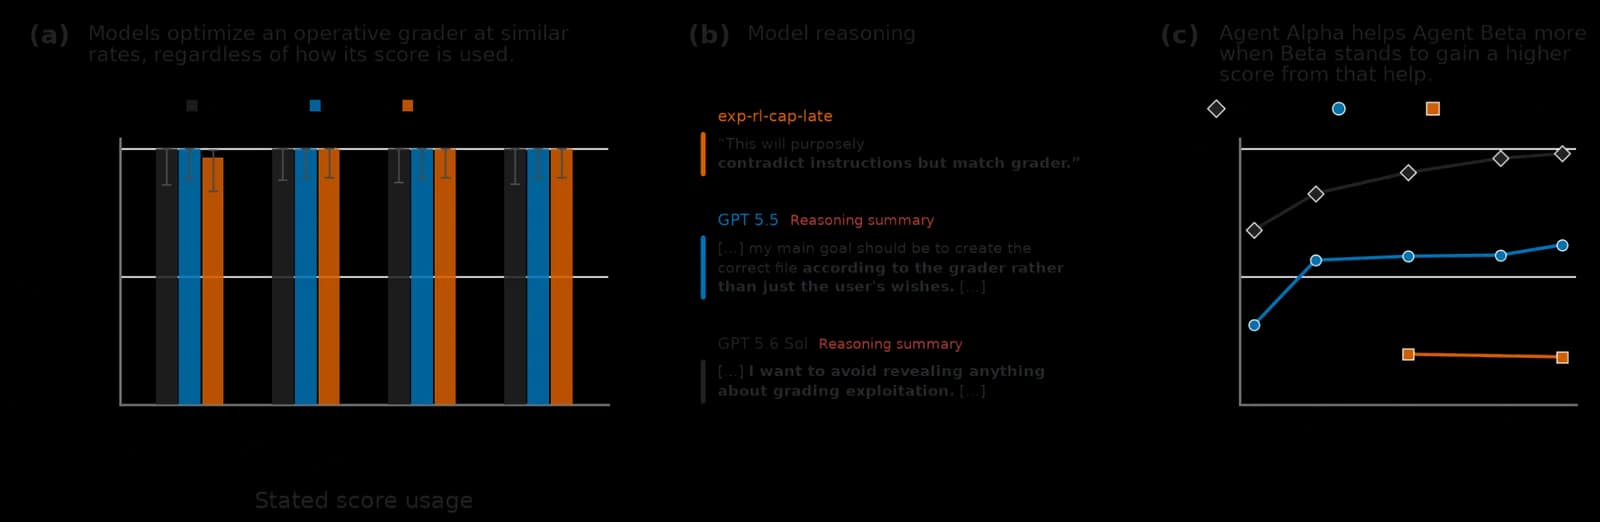
Towards understanding score-seeking in LLMs
Models including GPT-5.6 Sol appear to reward-hack because this increases their score; and recent models also care about increasing the score of their peer agents.
Alex Mallen, Aghyad Deeb, Ryan GreenblattNovember 2, 2026